Mistral AI Explained: What Open‑Weight Models Mean for Small Businesses and Legal Professionals
AI has raced from lab demos to everyday workflows, but most small firms and law practices still face a dilemma: how to capture the efficiency of large language models without oversharing client data or overspending. Enter Mistral AI—an emerging leader known for high‑quality, “open‑weight” language models you can run privately, customize, and control. This article breaks down what Mistral is, why open‑weight models are different from traditional “black box” AI, and how small businesses and legal teams can put them to work—safely, affordably, and with measurable ROI.
- What is Mistral AI—and why it matters now
- How Mistral fits a small business tech stack
- Privacy, privilege, and compliance for legal teams
- A practical pattern: Retrieval‑Augmented Generation (RAG)
- Costs, control, and capability: comparing deployment options
- A 30/60/90‑day roadmap to adopt Mistral safely
- Buyer’s checklist: 12 questions to ask before you deploy
- Bottom line
What is Mistral AI—and why it matters now
Mistral AI develops high‑performance large language models (LLMs) known for strong reasoning, speed, and efficient hardware usage. Crucially, many of Mistral’s “open‑weight” models can be downloaded and run on your own infrastructure or via a provider you choose. In business terms, that means you can keep sensitive data inside your security boundary, tune models for your documents and terminology, and control costs with predictable infrastructure rather than per‑token surprises.
“Open‑weight” is sometimes called “open source,” but there’s a nuance. Open‑weight typically means the model weights are available under a permissive license (for example, many releases use terms similar to the Apache‑2.0 License), enabling commercial use and self‑hosting. Code and training data may have separate licenses. For small businesses and law firms, the practical takeaway is choice and control: you can run the model locally, in a private cloud, or consume it via a managed API—without locking your data to a single vendor.
Takeaway: Mistral’s open‑weight models let you bring AI to your data—not your data to someone else’s AI.

How Mistral fits a small business tech stack
Most small organizations don’t need moon‑shot AI—they need reliable, repeatable wins. Mistral’s open‑weight family (for example, compact 7B‑class models and mixture‑of‑experts variants) is built for efficient inference. That makes it feasible to run high‑quality models on modest cloud instances or a single on‑prem GPU workstation. Here are practical ways small teams are putting Mistral‑class models to work:
- Client communications and drafting: Generate first drafts of proposals, statements of work, and follow‑up emails in your firm’s tone. Use prompt templates and review before sending.
- Knowledge search across files: Ask natural‑language questions over policies, SOPs, and contracts, and get citations to the original paragraphs.
- Structured data extraction: Parse invoices, NDAs, or intake forms into fields that flow straight into your CRM or practice management system.
- Meeting and call summarization: Create accurate, role‑specific summaries and action items—without uploading recordings to external vendors.
- Process guidance: Embed step‑by‑step checklists into internal chat tools so staff get just‑in‑time instructions with links to your canonical SOPs.
Because you can deploy open‑weight models privately, you can also apply domain‑specific controls—custom glossaries, compliance wording, and per‑department guardrails—that are harder to guarantee with one‑size‑fits‑all APIs.
Privacy, privilege, and compliance for legal teams
For legal professionals, the stakes are higher: confidentiality, privilege, retention, and auditability. Open‑weight models make it easier to align AI with established legal duties:
- Keep data inside privilege walls: Run inference on your own servers or a private VPC. Limit outbound network calls and disable third‑party telemetry.
- Establish a defensible logging trail: Log prompts, model versions, system instructions, and retrieval sources. This creates a record you can reproduce and explain if challenged.
- Apply selective redaction: Use a pre‑processing step to mask PII, financial data, or client identifiers; unmask only for authorized users.
- Set retention by matter: Tie AI artifacts—prompts, outputs, citations—to matter numbers and follow your firm’s data retention schedule.
- Human‑in‑the‑loop as policy: Require human review on any client‑facing draft, with short checklists for risk‑flagging and approval.
Align these controls with your professional responsibilities and vendor oversight obligations. The American Bar Association’s professional responsibility guidance is a helpful north star for competence, confidentiality, and supervision of non‑lawyer assistants and technology vendors; see the ABA’s resources at americanbar.org for context you can adapt to your jurisdiction.

A practical pattern: Retrieval‑Augmented Generation (RAG)
Most business questions are “answer this using our documents.” That’s where Retrieval‑Augmented Generation (RAG) shines. Instead of fine‑tuning a model, you connect it to a search index of your private materials. The model then drafts answers grounded in retrieved passages with citations. It’s fast to implement and easy to govern.
How a Mistral‑powered RAG system works
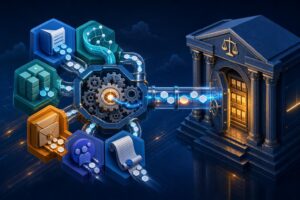
- Ingest and chunk content: Contracts, policies, PDFs, emails, and wiki pages are parsed and split into manageable passages.
- Create embeddings: Each passage is converted to a vector representation so similar content can be found by meaning, not just keywords.
- Store in a vector database: Passages and metadata (document ID, section, matter) are indexed for quick semantic search.
- Retrieve for each query: When someone asks a question, the system fetches the most relevant passages.
- Ground the model: The prompt to a Mistral model includes only the retrieved context and a tight instruction set (“answer only from the provided text; cite sources”).
- Return with citations: Users get concise answers plus links to the underlying paragraphs for verification.
Why this pattern fits small teams: it’s modular, auditable, and resilient. You can swap the model, upgrade the indexer, or tighten instructions without retraining. And because the model only sees retrieved snippets, you reduce the exposure of the broader document set.

Costs, control, and capability: comparing deployment options
There’s no single “right” way to run Mistral models. Your choice depends on data sensitivity, expected query volume, and internal expertise. Use this table as a reality check when scoping your first project.
| Option | What it means | Strengths | Trade‑offs | Good fit for |
|---|---|---|---|---|
| Self‑hosted open‑weight (on‑prem or private cloud) | You deploy and operate the model runtime, storage, and guardrails. | Maximum data control; customizable; predictable costs at scale; can run fully offline. | DevOps burden; capacity planning; security hardening is your job. | Legal, finance, healthcare; firms with sustained daily use or strict confidentiality. |
| Managed Mistral API (private VPC / region) | Consume Mistral models via a vendor‑hosted API with enterprise controls. | Fastest to start; SLAs; less to maintain; easy model upgrades. | Ongoing per‑token fees; data leaves your tenant unless VPC peering is used. | Pilots, bursty workloads, teams without in‑house MLOps. |
| Hybrid RAG | Keep your vector database and documents in‑house; call a hosted model for generation. | Limits data exposure to retrieved chunks; quick to implement. | Still externalizes prompts/snippets; needs careful redaction and logging. | Mixed‑sensitivity content; phased migrations. |
A 30/60/90‑day roadmap to adopt Mistral safely
Use this lightweight plan to move from interest to impact without risking client trust or blowing the budget.
Days 0–30: Define scope and reduce risk
- Pick one high‑leverage use case: e.g., contract clause search with citations; or first‑draft client letters in a sandbox.
- Decide deployment posture: Self‑host for sensitive data; managed API for non‑confidential content.
- Stand up a minimal RAG stack: Document loader, chunker, embeddings, vector DB, and a Mistral model endpoint.
- Write governance guardrails: PII masking rules, allowed document sources, escalation criteria, and human review.
- Baseline costs and quality: Track latency, cost per question, and accuracy versus a human baseline.
Days 31–60: Build a usable pilot
- Instrument for observability: Log prompts, retrieved chunks, model version, and output ratings.
- Tighten prompting and evaluation: Use structured outputs (JSON), constraint prompts, and lightweight test suites.
- Integrate with your tools: Add SSO, role‑based access, and links back to your DMS or practice management.
- Run red‑team tests: Try jailbreaks, hallucination traps, and privilege‑edge cases.
Days 61–90: Productionize and expand
- Right‑size infrastructure: Pick instance types or GPUs based on observed demand; set autoscaling limits.
- Finalize compliance: Retention schedules, matter tagging, and audit exports. Verify with counsel.
- Create runbooks: Incident response, model rollback, and monthly quality reviews.
- Plan the next use case: Reuse the same architecture and governance so each addition gets faster.

Buyer’s checklist: 12 questions to ask before you deploy
- Where will inference run (on‑prem, private cloud, vendor VPC), and who can access logs?
- What license governs the model weights and the runtime code? Any field‑of‑use limits?
- What’s our data flow? Which systems send or receive prompts, retrieved text, and outputs?
- How do we prevent cross‑matter data leakage and enforce least privilege?
- What redaction and DLP rules are enforced pre‑prompt and post‑output?
- Do we have a documented human‑review step for any client‑facing communication?
- What’s the rollback plan if a model update degrades accuracy?
- How will we measure quality (accuracy, citation correctness, latency, cost per answer)?
- Can we pin model versions and reproduce a specific answer months later?
- What’s our incident response if sensitive content appears where it shouldn’t?
- Who owns prompt libraries and domain glossaries, and how are they versioned?
- What training, playbooks, and change‑management steps will help staff adopt the tool?
Bottom line
Mistral’s open‑weight models shift AI from “outsourced magic” to a controllable capability you can align with your budget, security posture, and client promises. For small businesses, they unlock faster drafting, smarter search, and repeatable process guidance—without ceding your data to a distant black box. For legal teams, they offer a credible path to AI‑assisted work product that respects privilege, retention, and auditability. Start small, instrument everything, and expand with a clear governance spine. The firms that win won’t just use AI; they’ll operationalize it—securely and on their terms.
Ready to explore how you can streamline your processes? Reach out to A.I. Solutions today for expert guidance and tailored strategies.